I wouldn’t use an AI credit score to guide lending until four checks are complete: data quality, bias, decision explanations, and post-launch controls.
Here’s what I’d check before you put a model to work:
- Data: Reconcile financial records, verify repayment outcomes, and exclude information collected after the lending decision.
- Bias: Test for unequal outcomes across borrower groups and review inputs that may act as proxies for protected traits.
- Explanations: Confirm that each denial has specific, accurate reasons and a retrievable decision record.
- Monitoring: Assign reviewers, set alert thresholds, protect borrower data, and test backup steps for system failures.
I’d start with a limited rollout and human review, then check results against repayment outcomes. I’d also schedule reviews at least annually, with earlier checks after major changes. <u>The score should support lender judgment - not replace it.</u>
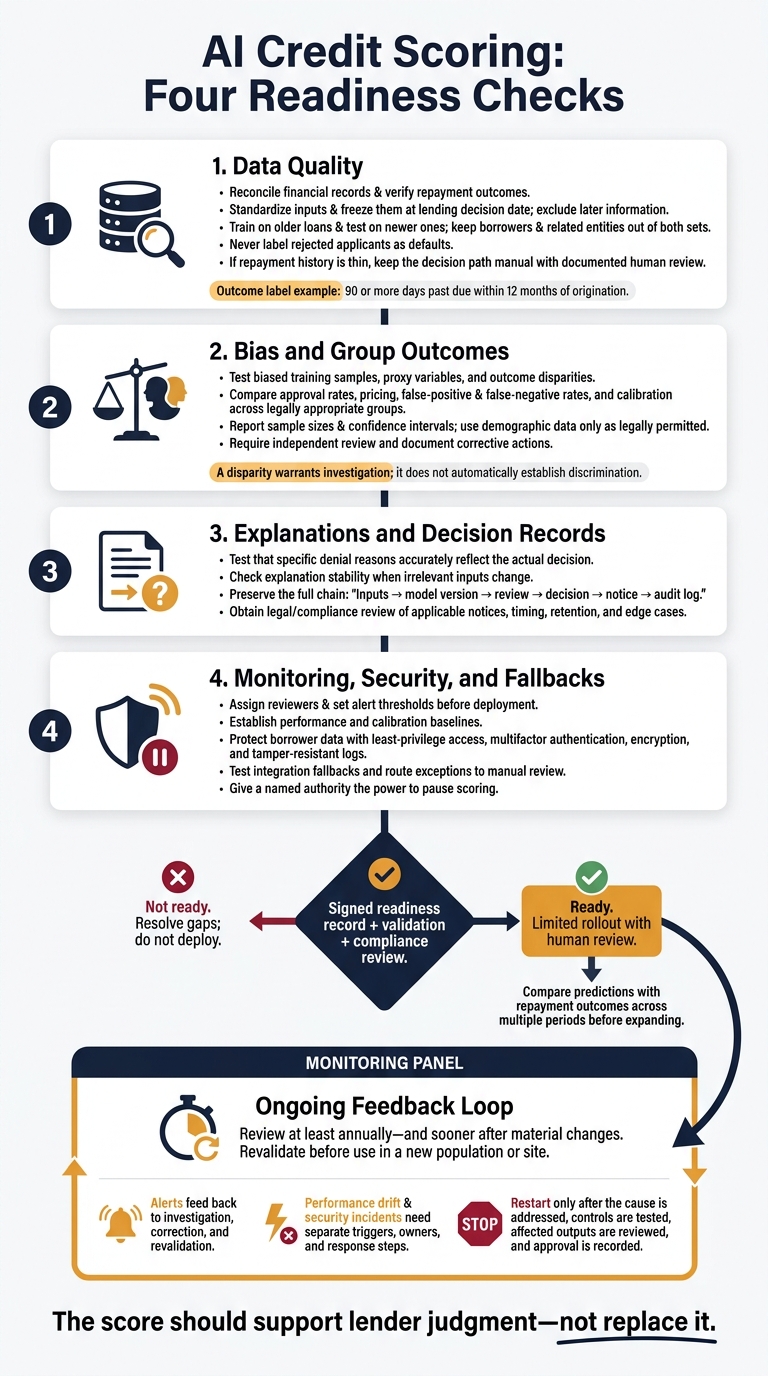
AI Credit Scoring: Four Readiness Checks
AI in Credit Scoring: Regulation, Risk, and Predictive Performance | Uplatz
sbb-itb-17e8ec9
Poor Data and Limited Repayment History
Clean books show capacity, not repayment performance. Accounting records show revenue, cash, expenses, and debt at or before a lending decision. Repayment outcomes show what happened next: on-time payments, delinquency, charge-offs, and recoveries. Models need both, but the two must stay separate. Start with clean data, then prevent leakage during modeling.
Find Missing Records and Data Errors
Audit records before calculating financial ratios. Track missing fields, outdated balances, conflicting borrower IDs, and unmatched deposits by source. Set clear rules for correcting errors or sending them for review.
| Data failure | Corrective control |
|---|---|
| Duplicate transactions inflate revenue or expenses | Match transaction IDs, accounts, dates, amounts, and counterparties. Reconcile entries against bank statements before removing them. |
| Expense categories differ across borrowers | Map source categories to a controlled chart of accounts. Keep the original values for audit. |
| Repayment outcomes are missing | Check servicing and lender records. Separate unfunded loans, reporting gaps, and transferred accounts; never assume “paid” or “defaulted.” |
| Intercompany activity inflates consolidated revenue | Match both sides and remove internal income, expenses, receivables, and payables from consolidated metrics. |
For multi-entity borrowers, assess the loan entity’s cash flow and debt service separately from the group’s financial strength.
Once the records are clean, standardize the inputs before training the model.
Standardize Inputs and Prevent Data Leakage
Keep a source register that lists each field’s origin, owner, update frequency, and allowed use. Reconcile bank transactions to ledger cash, debt to lender statements, and repayment records to servicing records.
Standardize currency, accounting basis, dates, and financial definitions. Check field types, ranges, how current the data is, and consistency across fields. Set retention rules and role-based access.
Define labels precisely - for example, 90 or more days past due within 12 months of origination. Specify how to handle extensions, recoveries, and incomplete observation periods. Freeze inputs at the decision date and exclude all later information, including collections notes and post-default balances.
Train on older loans and test on newer ones. Keep each borrower and its related entities from appearing in both sets. These controls test future performance without leaking borrower information.
Records of approved loans alone cannot show how declined applicants would have repaid. Document past approval policies and gaps in coverage; never label rejected applicants as defaults. When repayment history is thin, limit use to documented human review and keep the decision path manual.
Bias and Unequal Credit Outcomes
Clean data can still carry old lending bias. High accuracy doesn’t mean a model is free of bias. Past lending records may reflect unequal access, inconsistent underwriting, or discrimination - and models can carry those patterns into future predictions. A disparity warrants investigation, but it does not automatically establish discrimination.
Check Training Data and Proxy Variables
Check three separate risks: biased training samples, features that serve as proxies for protected characteristics, and outcome disparities. Location, industry, and similar business variables are not automatically discriminatory. Each needs a documented link to repayment risk, backed by validation.
Record each feature’s source, transformations, limitations, and less discriminatory alternatives. Keep a feature only when validation supports its use - not just because it improves overall accuracy.
| Bias source | Warning sign | Diagnostic test | Corrective action |
|---|---|---|---|
| Historical lending patterns | Approval or loss patterns mirror past disparities | Compare historical outcomes with independent repayment records | Reweight or rebalance data; remove unreliable labels; add human review |
| Underrepresented borrowers | Small samples, unstable estimates, or high rates of missing data | Check counts, confidence intervals, missing-data rates, and validation performance | Collect better data where lawful; use stratified validation; avoid unsupported segmentation |
| Location proxy | Location strongly changes decisions without a clear financial rationale | Test its association with protected groups and compare predictions with and without it | Use narrower, risk-relevant measures or remove the feature |
| Industry or customer segment | The model penalizes sectors or segments associated with particular demographic groups | Compare approval, error, and calibration rates by industry and customer segment | Document the cash-flow mechanism; constrain, transform, or replace the variable |
| Revenue mix | Predictions change sharply with revenue composition despite similar cash flow | Compare predicted risk at matched revenue, margins, collections, and liquidity | Use direct cash-flow measures; test whether revenue mix adds independent value |
| Proxy interactions | Combined features produce disparities that individual features do not | Run interaction, subgroup, and what-if sensitivity tests | Remove or constrain harmful combinations; add monitoring triggers |
Run these checks on training, validation, and production populations. Removing one suspected proxy does not address the risks created by features working together.
Test Group Outcomes and Review Disputes
Before launch and during recurring monitoring, compare approval rates, pricing, false-positive and false-negative rates, and calibration across legally appropriate groups. Calibration checks whether the same predicted risk corresponds to similar observed repayment outcomes.
Define which outcome counts as positive, and report sample sizes, confidence intervals, and trends across multiple periods. Use demographic data only as legally permitted. Restrict access and keep it separate from decision-making. Test intersecting groups only when samples support reliable estimates.
Require independent review of feature choices, group results, limitations, and corrective actions. Developer sign-off alone is not enough. Document escalation thresholds and provide a dispute process that lets trained reviewers correct errors and override unsupported decisions. Record the original output, supporting evidence, reviewer, date, and final reason. Check whether overrides cluster by group.
Use multiple fairness checks, then send the model for legal and compliance review before launch or material changes. These checks are the first gate. Next, make sure decisions can be explained and are documented, then monitor drift, security, and system failures after launch.
Unclear Decisions and Compliance Gaps
Even a fair model falls short if the lender cannot explain and document each denial. Using AI or third-party models does not remove adverse-action duties. U.S. rules differ by transaction type and lender role, so get qualified compliance review.
Choose Models With Testable Explanations
Choose a model your team can validate and explain - not just the one with the highest accuracy. Internal explanations should help reviewers trace how the model works. Applicant-facing explanations must state the principal reasons for the decision.
| Model approach | Transparency | Predictive flexibility | Documentation and review needs |
|---|---|---|---|
| Logistic regression or scorecard | Usually easier to connect inputs to outcomes and adverse-action reasons | More limited when relationships are highly nonlinear | Requires variable definitions, validation, monitoring, and compliance review |
| Decision tree or rule-based model | Reviewers can often see the rules directly | Moderate; complex trees can be hard to interpret | Requires version control, rule testing, and review of interactions |
| Gradient boosting, neural network, or ensemble | Can model complex relationships but may be hard to interpret | High, especially with large, varied datasets | Requires stronger validation, explanation testing, governance, and human-review controls |
| Third-party scoring model | Internal workings may be restricted or unavailable | Depends on the vendor’s design | Requires vendor due diligence, contract terms, documentation, performance evidence, and a contingency plan |
Test explanations before launch and after any material change. Use controlled input changes, local sensitivity analysis, and known test cases to check that the stated reasons actually drove each result. Also check whether explanations stay stable when irrelevant inputs change. Portfolio-level feature importance does not explain an individual denial.
Require vendor documentation and independent testing on your applicant population. A proprietary model does not exempt a lender from providing accurate explanations. Once you can test the explanations, record the reasons, notices, and audit trail for each decision.
Record Decision Reasons and Audit Details
The record must support both the adverse-action notice and later review. Document the full chain: inputs, model version, review, decision, notice, and audit log. Retain reason codes, notice content, delivery method and date, and audit IDs for adverse-action notices, reviewer checks, and audits. Keep records retrievable under applicable retention rules - not just internal policy.
Use specific reasons backed by the actual decision evidence, rather than a generic checklist. ECOA and Regulation B address covered credit discrimination and adverse-action obligations. FCRA duties may also apply when consumer-report information is used, including reporting-agency details, dispute rights, and score disclosures where required.
Business-purpose credit, consumer credit, guarantors, and mixed-purpose transactions can present different coverage and documentation questions. Before production, have legal/compliance reviewers approve reason mappings, notice templates, timing, retention, and edge cases for your organization’s role.
With documentation in place, monitor the model for drift, security issues, and system failures.
Model Drift, Security Risks, and System Failures
After launch, the work shifts from explaining the model to monitoring it. Business changes can weaken predictions even when the code stays the same. Borrower cash flow, payment timing, portfolio mix, and site expansion can all change repayment risk. Revalidate a model before applying it to a new population or site.
Monitor Results and Set Action Triggers
Before deployment, record baseline calibration and performance. Then compare input distributions, approval rates, delinquency, cash flow, and repayment outcomes against those baselines. Set action thresholds for missing data, overrides, group outcomes, and integration failures.
Use cash flow, returned payments, and payment delays as early warning signals, then back-test them against the original prediction window. Review models at least annually - and sooner after material changes.
| Signal | Likely cause | Responsible reviewer | Required action |
|---|---|---|---|
| Input distributions shift after an acquisition or a new location opens | New population or revenue cycle | Model owner and finance lead | Segment results and revalidate before broader use |
| Medical reimbursements or customer payments are delayed | External payment-cycle change or temporary liquidity pressure | Credit risk lead | Add contextual review and track repayment |
| Calibration worsens or delinquency exceeds forecasts | Conceptual drift, data error, or changed economic conditions | Independent validator or risk lead | Back-test, recalibrate, or suspend automated approvals |
| Missing or stale fields increase | Failed integration, changed source system, or weak data controls | Data owner and engineering lead | Repair feeds; use a tested fallback or manual review |
| Override rates jump sharply | Policy mismatch, threshold problem, or outputs reviewers do not trust | Credit policy owner and compliance | Review overrides; validate before revising or retraining |
| Group approval or repayment outcomes diverge unexpectedly | Population shift, proxy effect, or disparate impact | Compliance and model-risk reviewer | Document findings and apply corrective controls |
| Unauthorized access or unusual downloads occur | Excessive permissions or compromised credentials | Security lead and incident team | Contain access, preserve logs, notify required parties, and suspend affected processing |
| Vendor changes a model, API, data source, or business rule without approval | Weak change management or incomplete contract controls | Vendor owner and model-risk lead | Document and validate changes; escalate for approval |
For each incident, assign an evidence owner, response deadline, escalation path, and closure standard. Record the investigation, corrective action, and revalidation results. Give a named authority the power to pause scoring. Restart only after the cause is addressed, controls are tested, affected outputs are reviewed, and approval is recorded.
Performance drift and access failures need separate triggers, owners, and response steps.
Protect Data and Validate Changes
Protect the scoring pipeline with least-privilege access, multifactor authentication, encryption in transit and at rest, and tamper-resistant access and change logs. Avoid collecting unnecessary medical data. Use aggregated reimbursement or cash-flow measures when they provide enough information.
Have counsel assess applicable financial-data, health-data, breach-notification, contractual, and state-law obligations. Review scoring vendors’ security controls, subcontractors, retention practices, incident response, and continuity plans. Require validation evidence, access for assessments, and advance notice of material changes.
Test integration fallbacks before launch. Failed feeds must flag stale records and use an approved fallback - not silently substitute defaults. Send exceptions to manual review. Material changes to models, integrations, data sources, or business rules require impact testing, revalidation, a rollback plan, and documented approval.
Conclusion: Check Readiness Before Launch
Before launch, turn the controls for data quality, bias, explainability, and drift/security into a formal go/no-go checklist. Use scores to inform - not replace - cash-flow analysis, repayment-capacity review, collateral review, guarantor review, or underwriting judgment.
Complete a Model Readiness Checklist
Require a signed readiness record with documented controls and review dates. Test whether adverse-action reasons accurately reflect the factors actually considered or scored. Do not deploy until the team can explain each control.
After validation and compliance review, start with a limited rollout that includes human review. Compare predictions with repayment outcomes across multiple periods before expanding. Document unresolved risks and the conditions that must be met before broader use.
Prepare Borrower Records for Lender Review
Once the model passes readiness review, assemble the borrower file for the lender. Include reconciled books, entity-level financial statements, cash-flow reports, debt schedules, tax filings, and explanations for unusual swings.
For multi-entity borrowers, also include ownership details, intercompany transactions, guarantees, distributions, and liabilities. These records help lenders verify repayment capacity and check the model’s inputs against the underlying business.
FAQs
How much repayment history does an AI credit model need?
Startups don’t need a long repayment history to use AI credit models. These models assess creditworthiness through alternative data and behavioral patterns, including cash flow, bank transactions, and payment behavior.
Data quality, consistency, and access matter more than how far back the records go. Clean, integrated bookkeeping and consistent data tagging help models analyze risk accurately, even without a lengthy credit file.
How can startups balance prediction accuracy and fairness?
Startups can balance prediction accuracy with equitable credit decisions by using explainable AI tools like SHAP or LIME. These tools show how inputs affect each decision. Pair ensemble methods with thorough, automated bias testing, check that datasets represent the people being assessed, and use diverse training data to help prevent historical bias.
Keep humans involved in high-stakes decisions, with the ability to intervene to support regulatory compliance and ethical standards.
What should a limited AI credit scoring pilot measure?
Set clear acceptance criteria before launch. Measure model performance using precision, recall, and AUC-ROC, and check system integrity and data quality. Monitor input data distributions, shifts in feature importance, and changes in output distributions.
Verify explainability, auditability, and controllability. Record design decisions, map data lineage, and test for bias to support outcomes that can withstand scrutiny and meet regulatory requirements.